Microsoft 365 November 12th Outage Explained
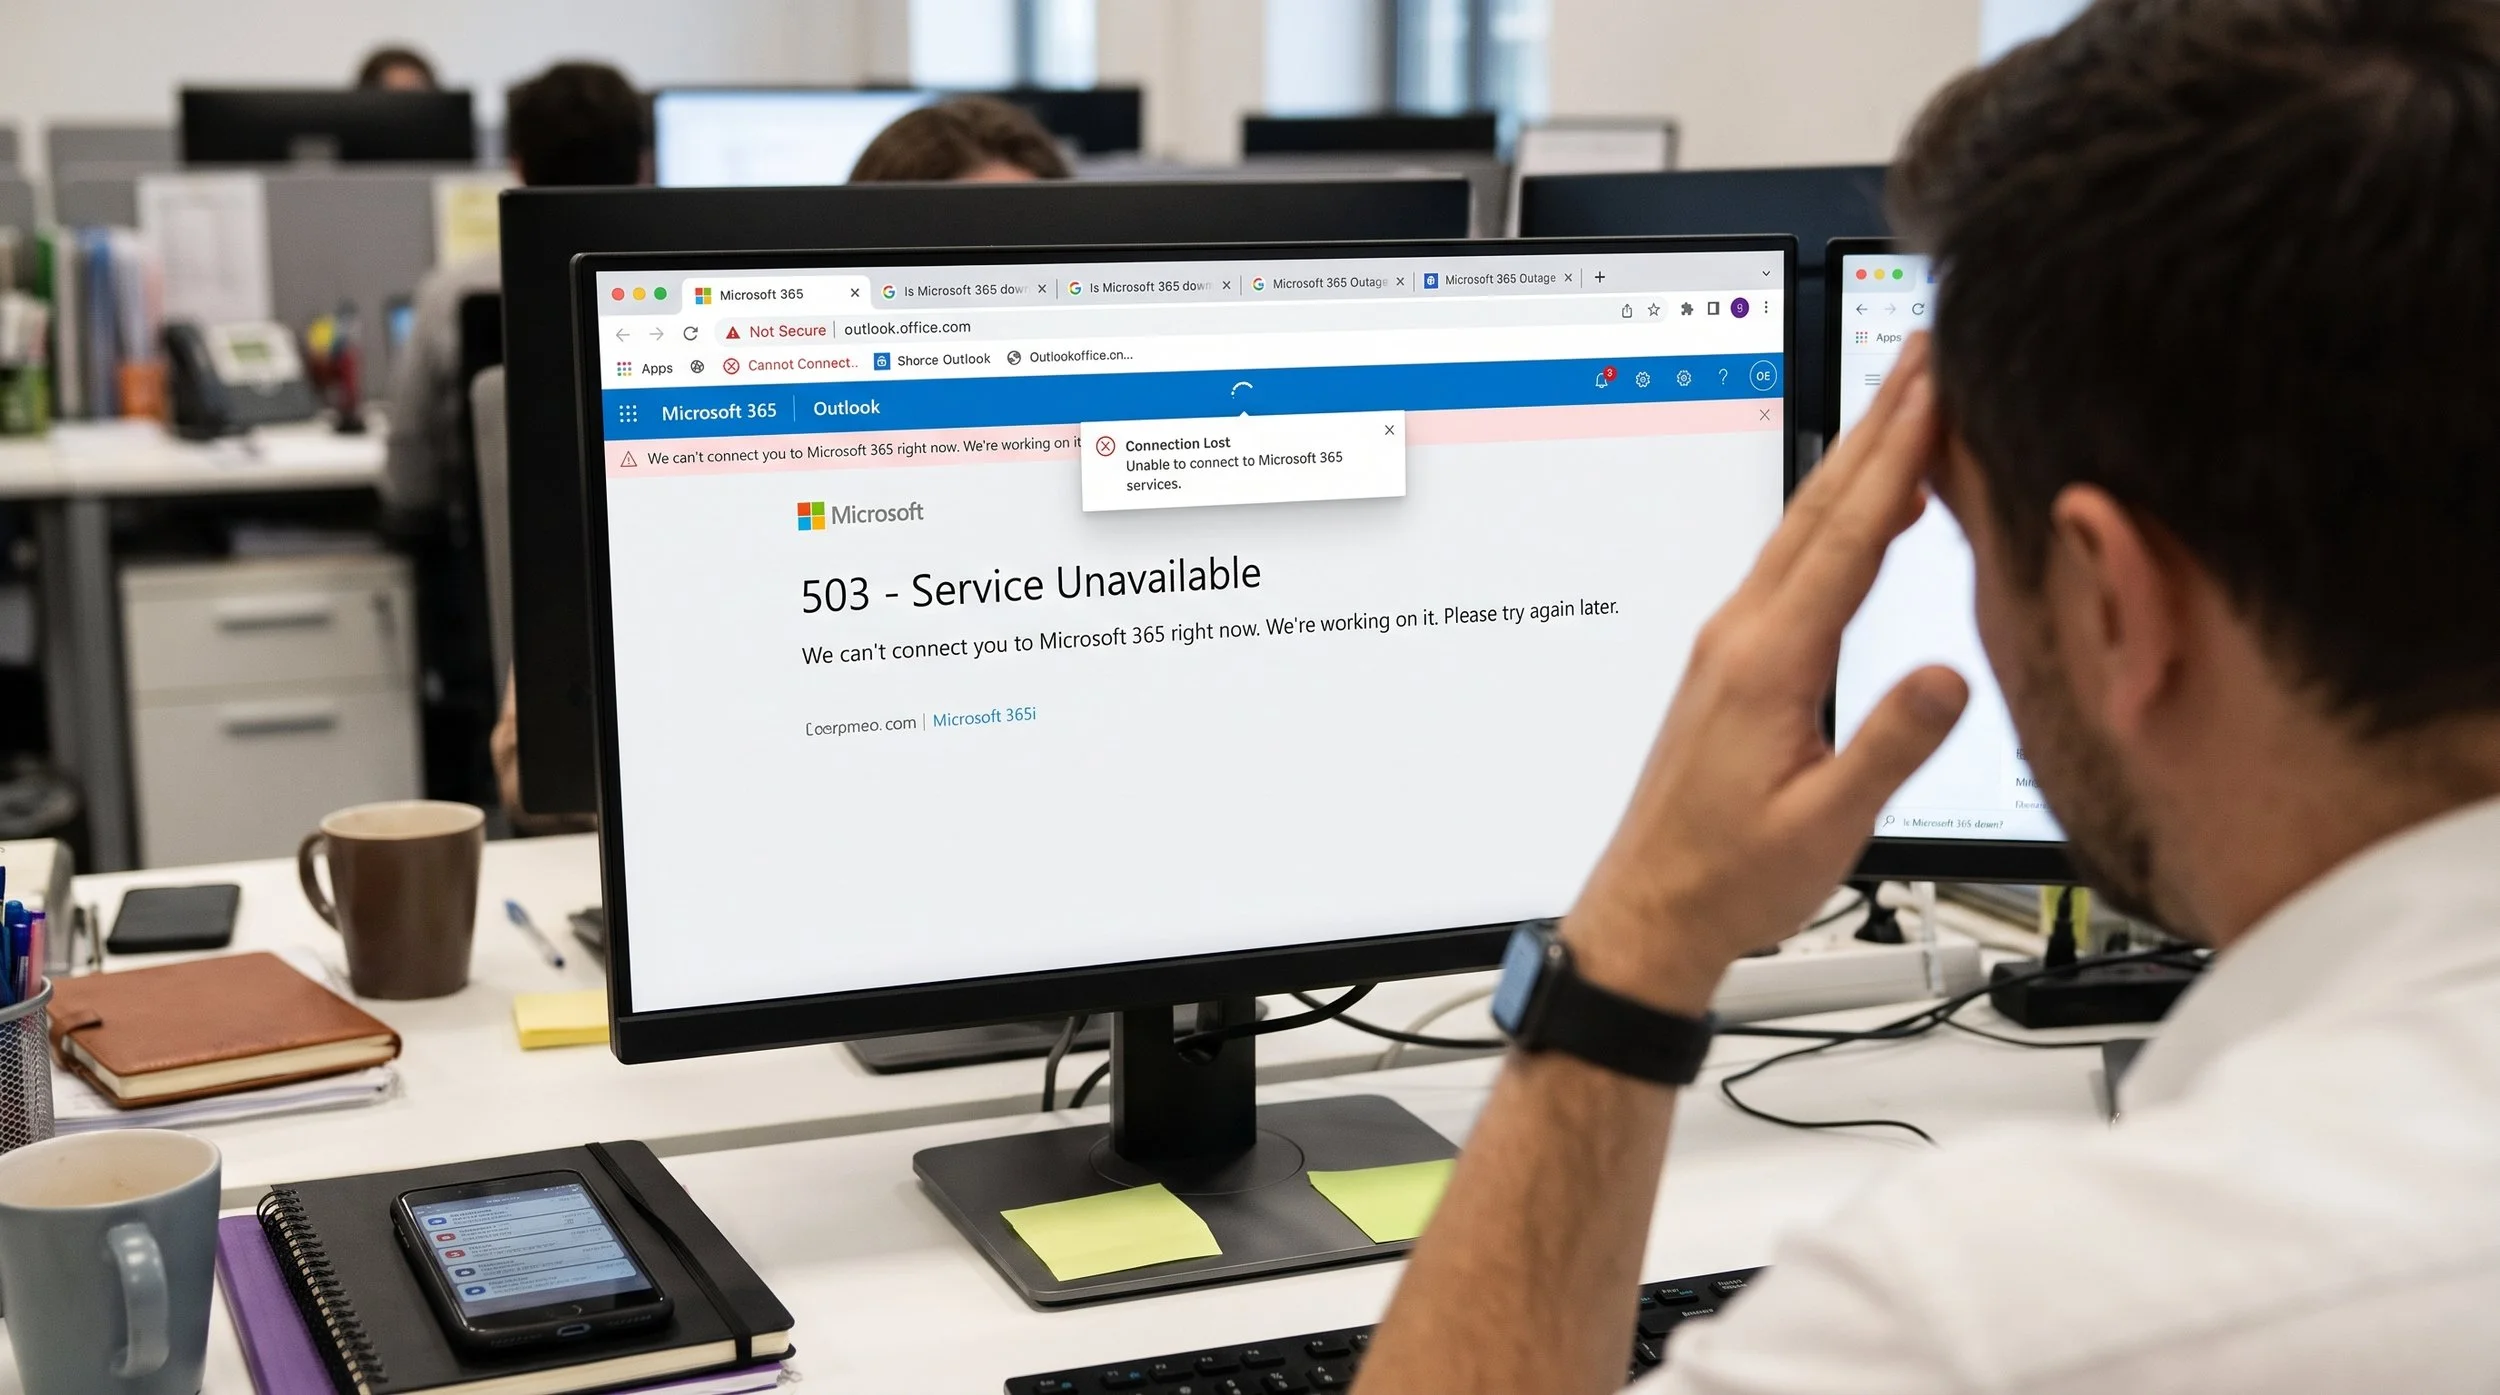
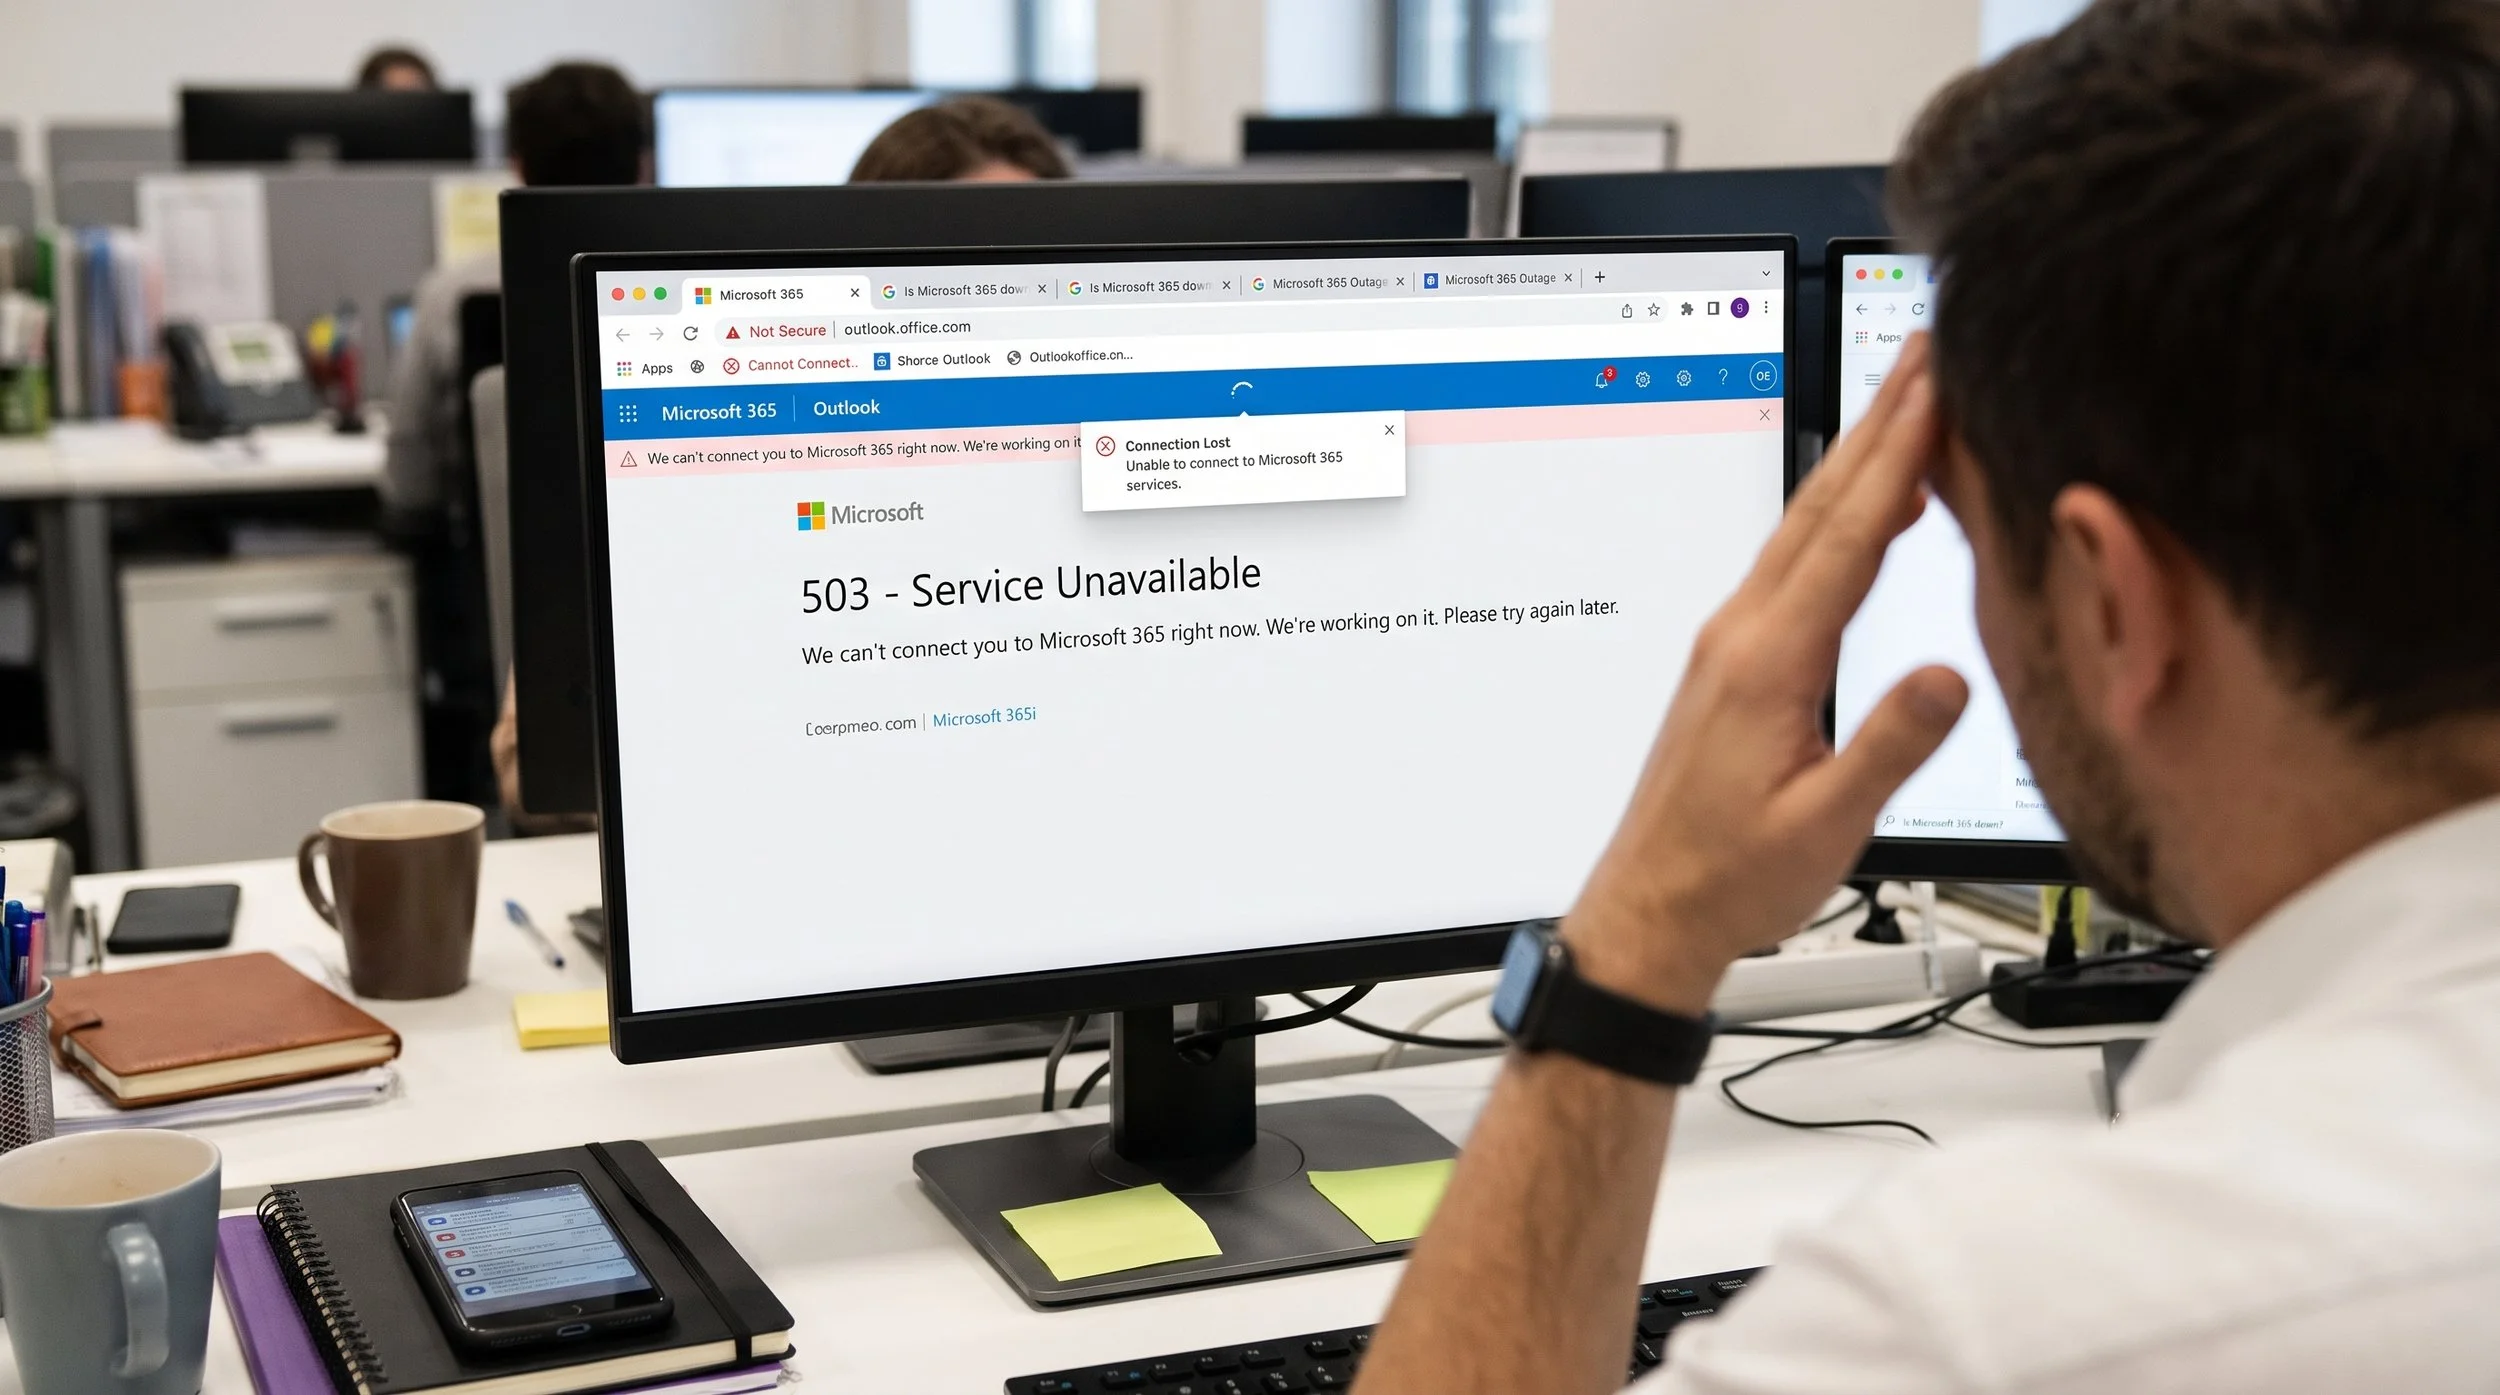
Imagine software that sustains global communication, file storage, and AI workflows for businesses and government institutions worldwide—and imagine a single infrastructure glitch that brings global productivity to a standstill. That reality happened dramatically last week, on November 12, 2026, when a substantial Microsoft 365 outage disrupted access to Outlook, Exchange Online, Teams, SharePoint, OneDrive, and Copilot across at least 74 countries for more than 24 hours.
Despite early speculation of a cyberattack — which, by the way, came two days after Microsoft released its immense November Patch Tuesday update. The company has claimed and confirmed that the entire incident was self-inflicted. At its peak, more than 80% of Microsoft's affected servers were unresponsive.
What Were the Hidden Flaws That Triggered The Domino Effect?
According to Microsoft executives—specifically Vice President of Copilot, Agents, and Platform Charles Lamanna—the sudden digital collapse wasn't caused by a single bad update. Instead, three independent issues collided within the network's gateway, situated directly in front of Microsoft 365, and became the primary culprit.
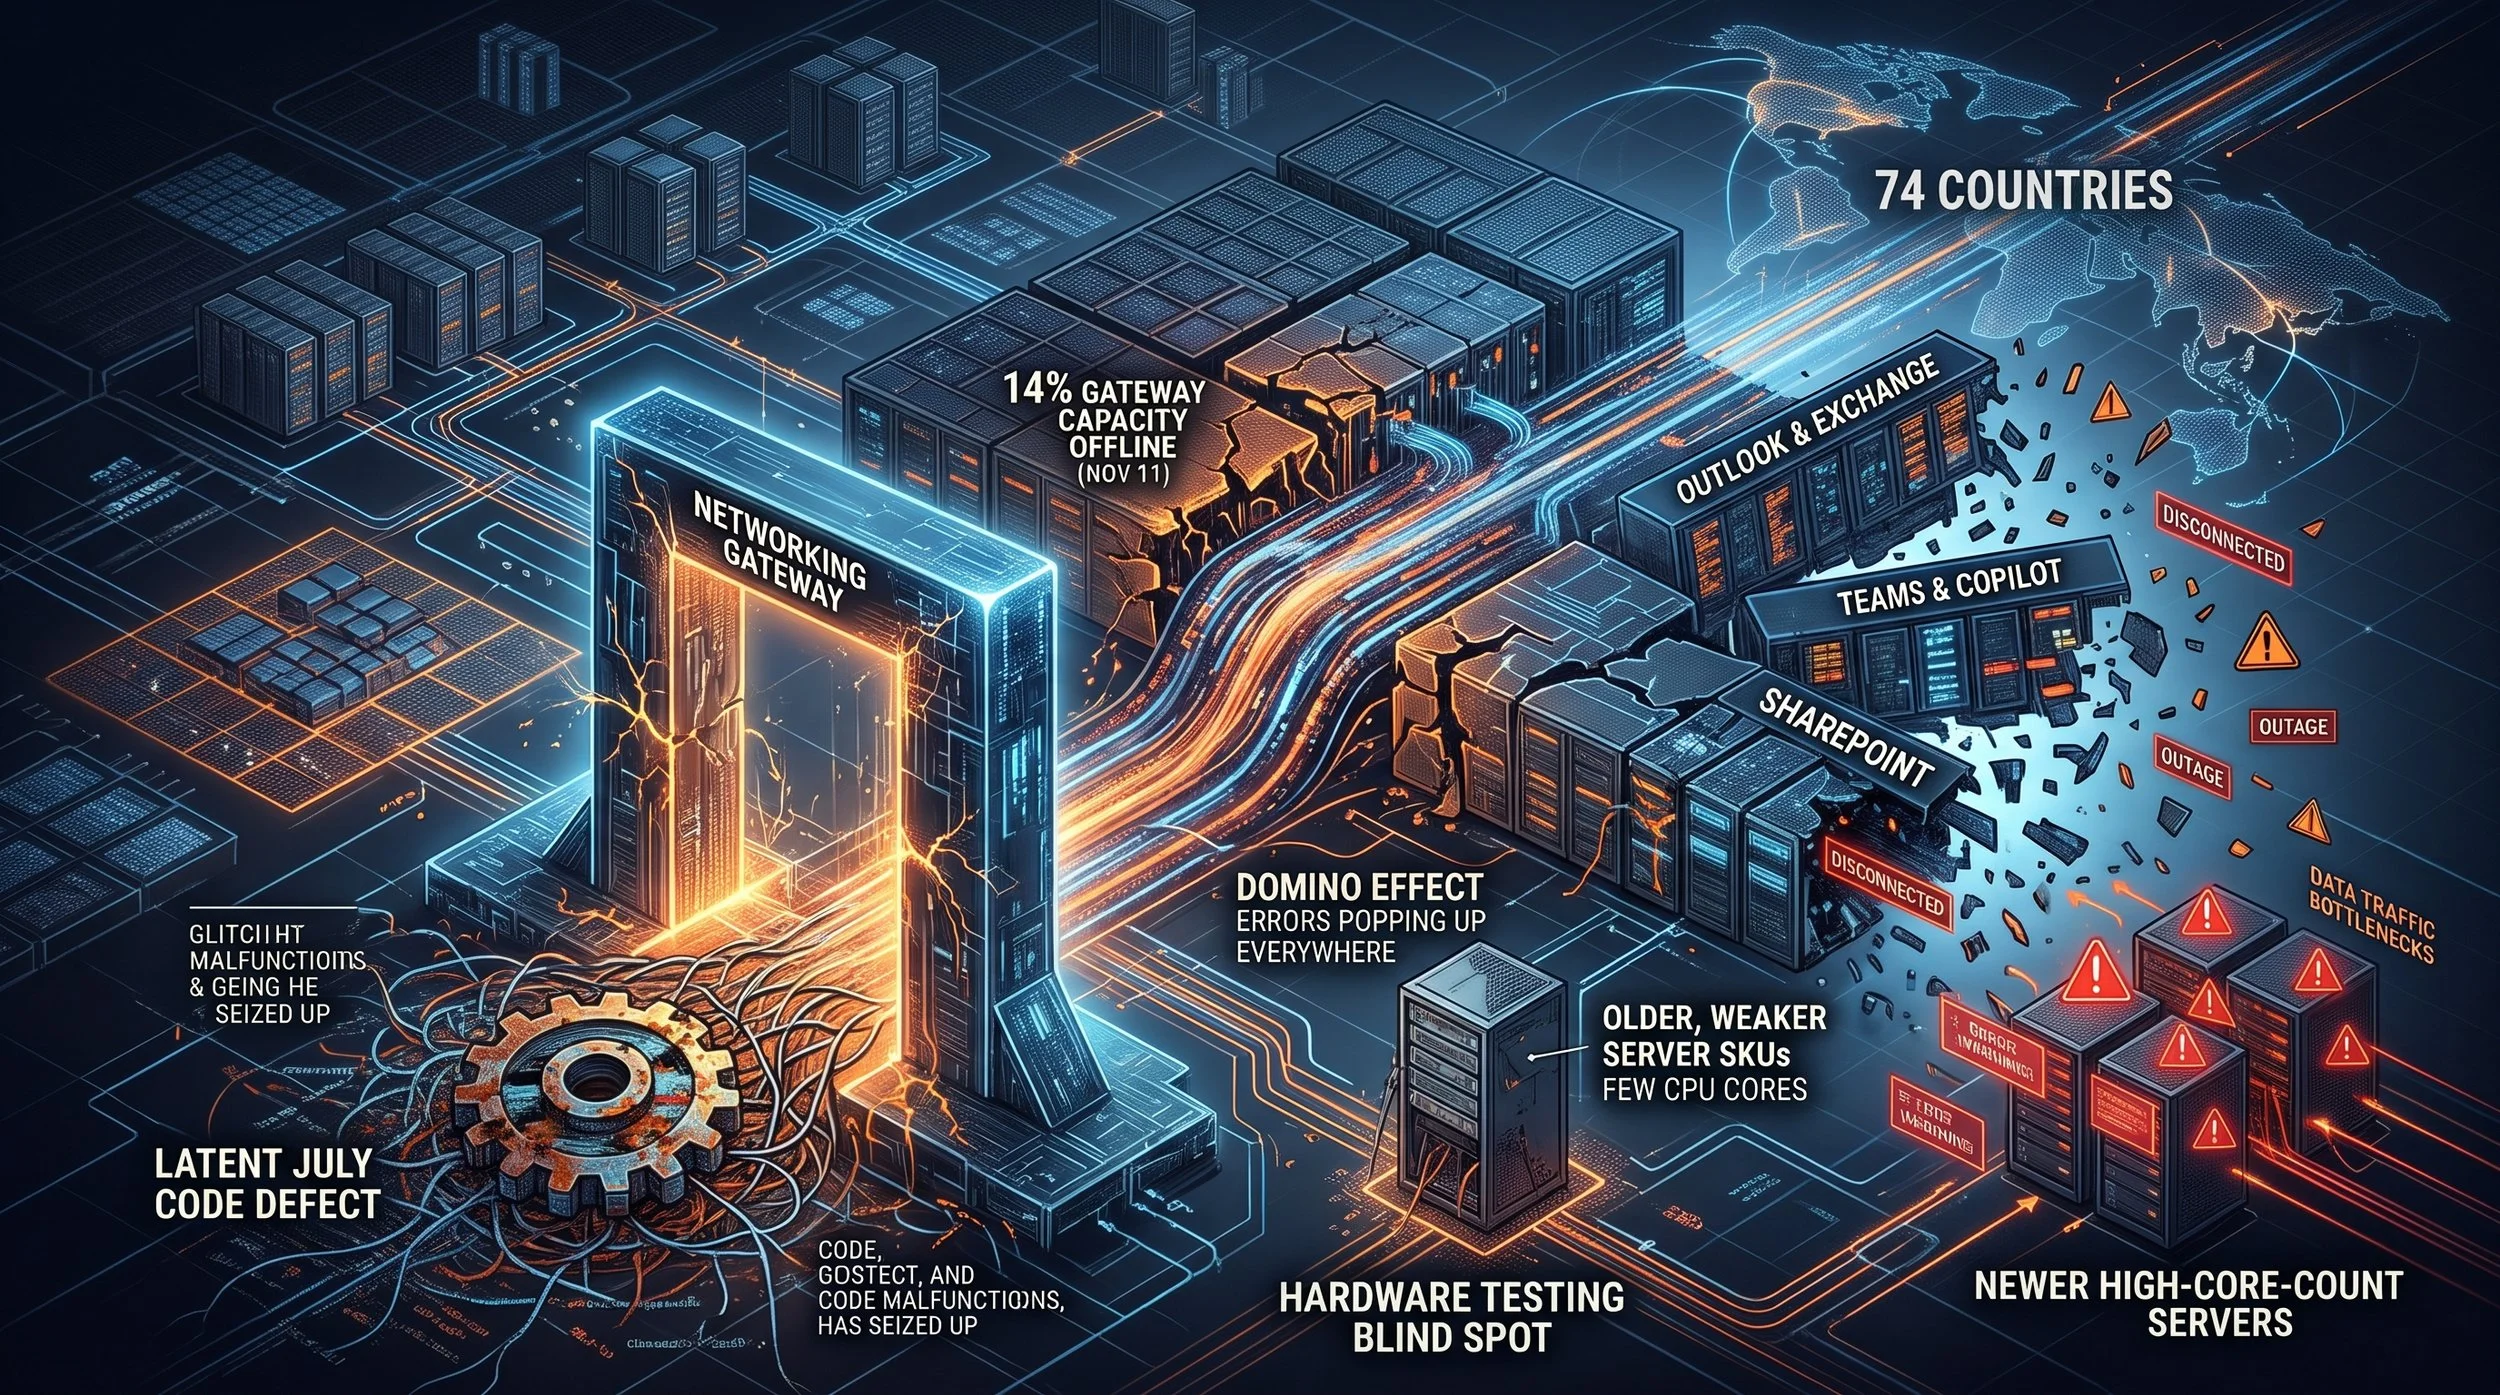
Hidden Flaw Number One: A July code change sat dormant in Microsoft's updated network configuration, containing a latent defect. Because the exploit bug only manifested under intense server stress, it went undetected in production for three months.
Hidden Flaw Number Two: A Load Testing Blind Spot: Microsoft's stress tests rely on older server hardware SKUs with low CPU core counts. In live data centers, the defect degraded performance far more aggressively on newer, high-core-count servers—rapidly overwhelming the processor responsible for securing network connections.
Hidden Flaw Number Three: Preexisting Capacity Loss: Just one day earlier, on November 11, an unrelated technical issue knocked 14% of the networking gateway's server capacity directly offline.
U.S. user traffic surged and peaked around midday on November 12; the remaining 86% of the gateway hit the same stress threshold that triggered the July defect.
What followed was a barrage of failures. As the overloaded servers failed automated health checks and went offline, Microsoft's traffic-routing systems did what they were designed to do: redirect incoming requests to healthy servers. Instead of relieving the pressure, that sudden influx of rerouted traffic pushed the remaining healthy nodes past the same threshold. As a result, it knocked out four-fifths of the fleet in under two hours.
Why Did The Email Stay Down Long After Recovery?
While apps such as Teams, OneDrive, and SharePoint regained their ability to reroute traffic right off a faulty gateway and were stabilized within hours, Outlook and Exchange Online remained disabled well into November 13 and 14.
Modern chat and web apps are built as "fail-fast" mechanisms—if the connection drops, the user refreshes or retries once the servers reboot. The entire email infrastructure, by contrast, is engineered never to drop a message in transit. Meanwhile, during the outage, billions of inbound and outbound emails accumulated in deferred retry queues, which explains why you couldn't use email for days. Once engineers rolled back the problematic network configuration, Exchange servers had to carefully throttle and drain a massive multi-hour backlog without triggering a secondary traffic spike.
The Concluded Takeaway
The November 12th outage reminds us that even Microsoft's modern IT infrastructure isn't impervious to critical vulnerabilities.
Redundant architectures can be toppled by a subtle interaction between legacy code, hardware diversity, and automated failover systems. For businesses, this incident is an alarming reminder that cloud resilience doesn't just happen in Microsoft data centers—it requires out-of-band communication backups and well-organized contingency plans for when your personal digital workspace goes offline.